

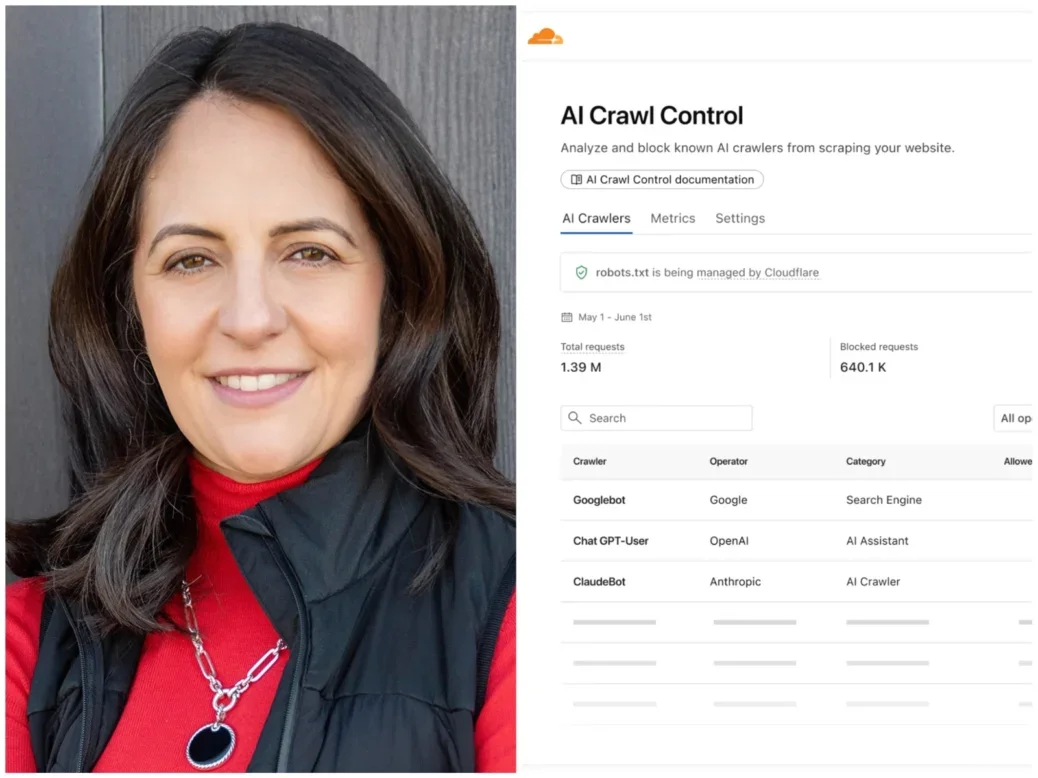
Creating “reliable scarcity” by blocking companies from scraping content for AI uses is leading to more licensing revenue, according to internet hosting giant Cloudflare.
Last year Cloudflare, which is used by 20% of websites worldwide, began to block AI crawlers by default for its customers unless they choose to allow them, for example because they have a content licensing deal or a clear value exchange such as Google search.
Cloudflare said its technology would allow a “pay-per-crawl” model which allowed website owners to charge a fee to the AI crawlers they let in.
Pay-per-crawl remains in closed beta testing with publishers across a range of content types taking part and sharing feedback.
Cloudflare said it will now shift its default position to “pay-per-use”, which is still at a very early stage, so publishers receive compensation if their content is surfaced in AI answers or otherwise directly creates value.
It has also just launched an AI visibility dashboard which it says allows publishers to track how often their content is appearing in answers from the likes of ChatGPT and Claude.
People Inc chief executive Neil Vogel told investors this month that the publisher is seeing “real momentum” in AI licensing and cited its ability to block scrapers using Cloudflare.
“People are understanding the value of our content because we are able to restrict almost everybody from using our content using our Cloudflare blocking,” Vogel said. “And they have to pay for it. And when people have to pay for it, it seems they’re really coming to the table.”
Vogel said previously that People Inc was blocking “almost all AI crawlers other than OpenAI, where we have a deal, and Google where we can’t block them because they use one crawler for search and AI”.
Cloudflare chief strategy officer Stephanie Cohen told Press Gazette People Inc is “not alone”. She added: “We’ve seen lots of our customers use our tools so that they can create reliable scarcity for their content, and then negotiate better deals. And so that part of the ecosystem really seems to be moving.”
Cloudflare has cited the Financial Times, The Atlantic, Ziff Davis, Conde Nast and Associated Press as other publishers working with it to do deals with AI companies.
But Cohen said this is not only for large publishers and noted local or other niche titles in areas like healthcare have information that AI wants and no-one else has. She said there are local news sites on Cloudflare’s network seeing a “path to having more licensing revenue than having ad revenue”.
She cited the information power of Park Record, which covers the ski destination of Park City in Utah and is owned by Cloudflare co-founder Matthew Prince.
“If you want to know what restaurant to go to on Main Street in Park City, Utah, there’s only so many places you can go for that information, for that information to be accurate, and so it’s kind of the quintessential thing that if you block it, AI needs to pay for it to get it, because users will be going on vacation and will want to know where to go…”
Pay-per-crawl versus pay-per-use
Cloudflare began testing the new pay-per-use model with Ceramic.ai, where publishers can get paid every time their content appears in search results if they opt in, and You.com, which is letting agents pay on demand for individual pieces of premium content to be delivered in AI answers for enterprise users.
Cohen said Cloudflare started with pay-per-crawl because it was the “easiest thing to measure: you know it happens”.
But she added: “Pay-per-use is a better signal of quality. If you’re scraping something, that doesn’t necessarily mean you’re using it, so using it is a better signal of quality. Over time, however, I would expect that crawling and use converge. The chances that you’re going to keep crawling something that you don’t use are probably unlikely…”
This will have the added advantage of helping to cut down on unnecessary crawling, Cohen continued.
“Our data shows us that more than half the time, an AI crawler is accessing information they’ve already accessed, and it has not been updated since they last accessed it. That’s wasteful from their perspective. It’s wasteful from the site owner’s perspective. It’s wasteful from the world’s perspective.”
Cohen said this is why Cloudflare has launched a research project with OpenAI to explore how content from participating websites can “help AI search engines discover and index relevant content on the open web more effectively”.
She said Cloudflare would check “if a site has been updated to basically tell them when it makes sense to crawl and when it doesn’t make sense to crawl so they’re only accessing information if it’s been updated, which we think will save lots of trees and energy and and money”.
‘There are not random bots getting through’
There are concerns in the industry that blocking the “polite” (meaning clearly identified) AI bots is not enough as scrapers often hide as humans, route between different browsers or come via residential networks, for example.
Tollbit’s latest State of the Bots report said: “Bots are shockingly effective at evading cybersecurity protections and paywalls; we observed them impersonate Google and others, rotate IP addresses, and appear to use residential proxies, hammering publishers with bot traffic.”
People Inc chief innovation officer Dr Jonathan Roberts wrote in the report that the publisher is blocking “tens of thousands of unique bad bots every day”.
He said “the most aggressive actors” go through each of these stages and are blocked at each one: they send a named crawler, then an anonymous one, then a crawler that spoofs Googlebot which is allowed, and then a crawler that attempts to look human by scrolling the page and executing code but fails at a human challenge.
Finally, Roberts said: “They send multiple crawlers through residential internet connections and mobile devices. Because these home proxy networks use legitimate IP addresses they are extremely difficult to identify as being compromised by bad actors and therefore block. We are able to block some of this activity, but not all.”
Cohen said “most” Cloudflare publisher customers have moved to blocking AI bots by default and allowing only those with whom they have deals. “In those cases, there are not random bots getting through.”
Asked how Cloudflare can guarantee it is blocking everything unwanted, Cohen said: “We strongly believe that when a customer blocks using our tools, that the block works. And in the few cases where we’ve had problems, we’ve publicly talked about it because it is very rare.”
She cited Cloudflare’s criticism of Perplexity last year which alleged: “Although Perplexity initially crawls from their declared user agent, when they are presented with a network block, they appear to obscure their crawling identity in an attempt to circumvent the website’s preferences.”
Cohen added that Cloudflare is “continuing to improve” bot management product Precursor, which became widely available last month. It runs inside web browsers so it can monitor user sessions and make it harder for bad actors to fake human behaviour, ultimately stopping evasive bots.
She explained: “There are certain signals that we would have only gotten at certain intervals on a website, meaning if you tried to log in, if you tried to pay for something… but now we’re going to be doing more constant monitoring, and it just makes the bot management product much smarter.”
Cohen also said that because Cloudflare works with so many websites, “there are so many things we see that it’s very difficult for people to evade a block”.
She did, however, warn that publishers may have “leaky buckets” without realising: for example, from syndicating their content to other websites.
“It’s not that if you block, the block doesn’t work. The block works, and when it doesn’t, we write about it all the time and publicly shamed people not behaving on the internet. But there are other places where you just have to look to see, like, is my content showing up in these other places, and how do I stop that from happening?”
Cloudflare has said that from 15 September, mixed-purpose AI crawlers that combine search and training will be blocked by default on pages with adverts. This would include Googlebot, which indexes content for search as well as its AI products like AI Overviews, unless the tech company separates its crawlers before then as it has pledged to do so.
Cohen said the reason for blocking mixed crawlers is that “we want to make sure that sites have the ability to be discoverable without giving their content away for free… when a company has three crawlers, for example, one for training, one for search, and one for agent or user, the site owner has more transparency around the intent, like why is the crawler coming to me, and has the ability to block or allow them at the network levels”.
The two-and-a-half month gap between announcing Cloudflare’s intentions and implementing them, Cohen said, was because “the goal is not to block. The goal is to actually get to a place where a sustainable ecosystem can emerge.”
Email pged@pressgazette.co.uk to point out mistakes, provide story tips or send in a letter for publication on our "Letters Page" blog
